Benchmark
Performance, proven.
Every claim on this page is backed by a public benchmark or production telemetry.
SWE-bench Verified
Hit Rate
~81%
Context Compression Rate
~14.84x
Error Rate
~<0.5%
Semantic cache that actually hits.
InferGrid's semantic cache intercepts repeated and near-duplicate prompts before they reach the model — cutting latency and cost without measurable quality loss.
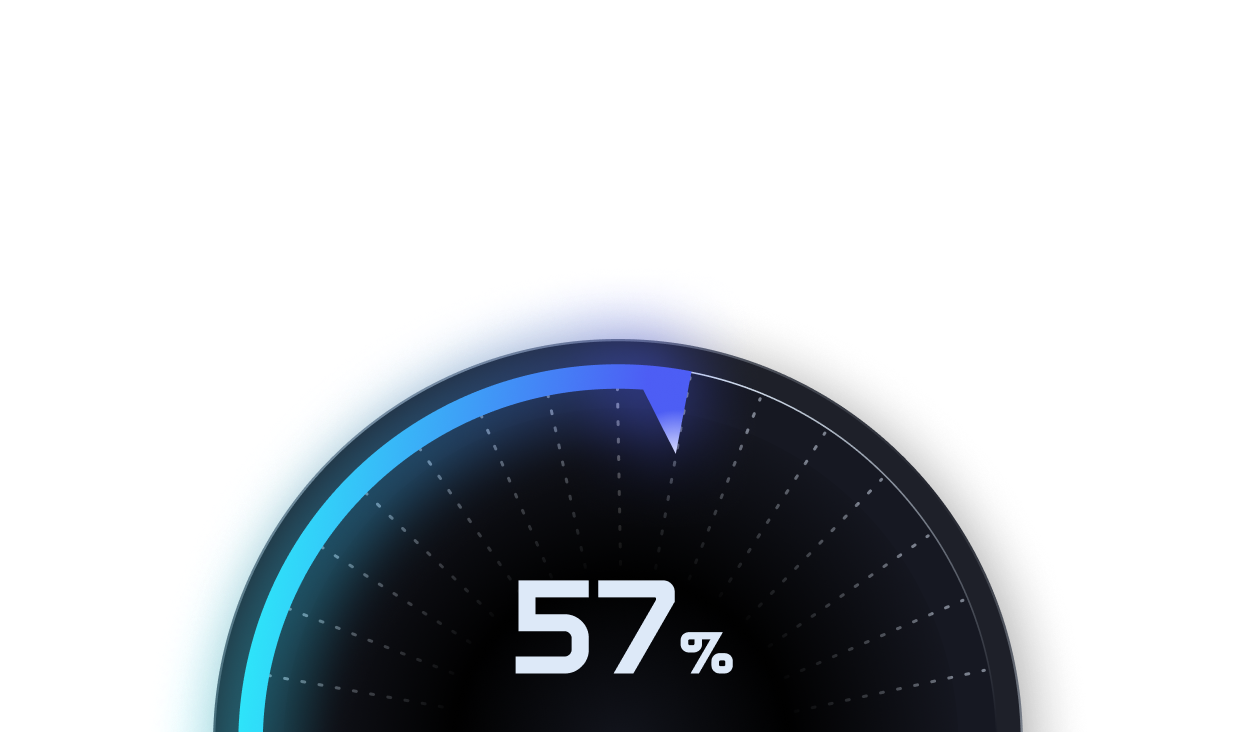
57% hit rate at <0.5% error
On the open SemCacheLMArena evaluation, InferGrid intercepts over half of all requests with a semantic match — while keeping answer-level error below 0.5%.
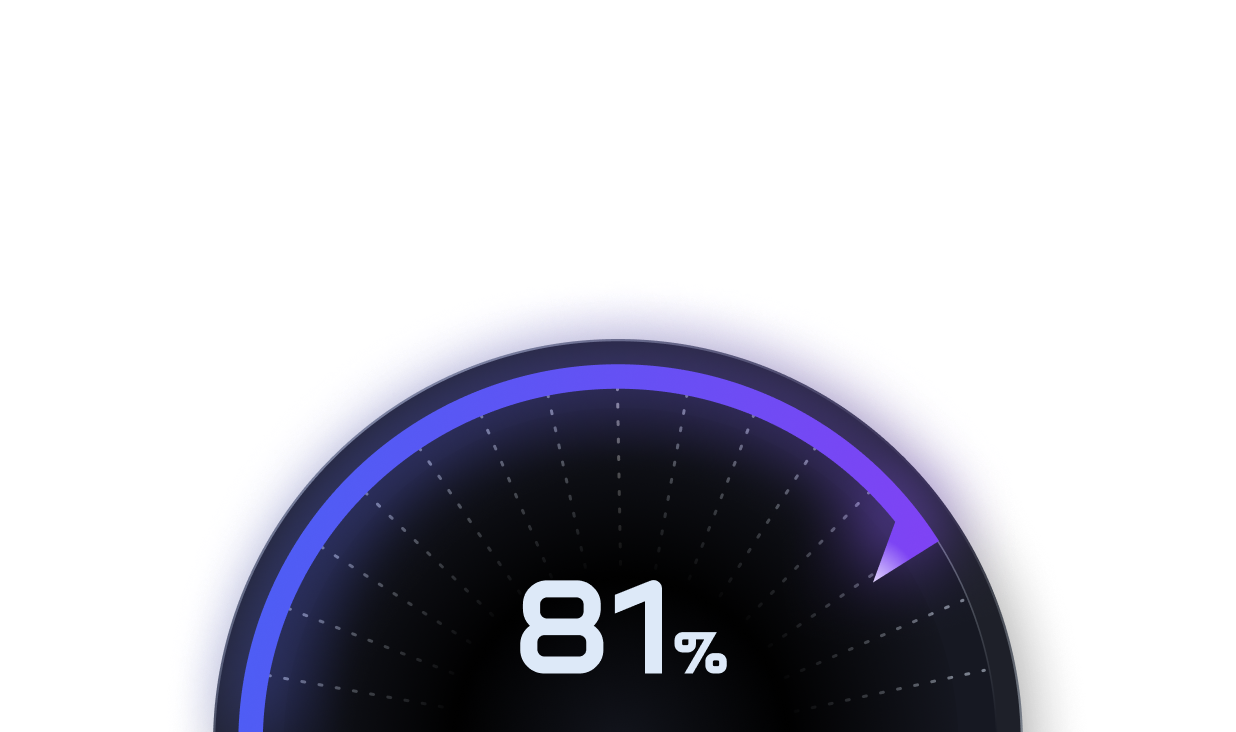
81% hit rate at <1% error
Across live production workloads, real-world repetition patterns push the hit rate even higher — 81% of requests served from cache with under 1% answer divergence.
Fewer tokens in, same answers out
InferGrid compresses context windows before inference — removing redundant and
low-signal content while preserving task-critical information, validated on SWE-bench
Verified.
Across the SWE-bench Verified task suite, InferGrid's compression pass removes between 23% and 54% of
input tokens — with no degradation in task completion quality.
Compression didn't just preserve quality — it improved task success by 3.5 percentage points.